Library
Knowledge Base
Browse our curated collection of insights, research, and practical frameworks.
framework
13 minYour Agent Didn't Fail at the Tool Call. It Failed at the Plan.
Sun et al. (2026) introduce Agent Planning Benchmark: 4,209 multimodal cases across 12 models. GPT-5 holistic plan correctness is 74.5% vs GPT-4o's 19.5%. Extra tools drop GPT-5 to 67.0% and spike tool-use errors from 2.3% to 15.8%. Constraint violation remains 16%+ even at the frontier.
framework
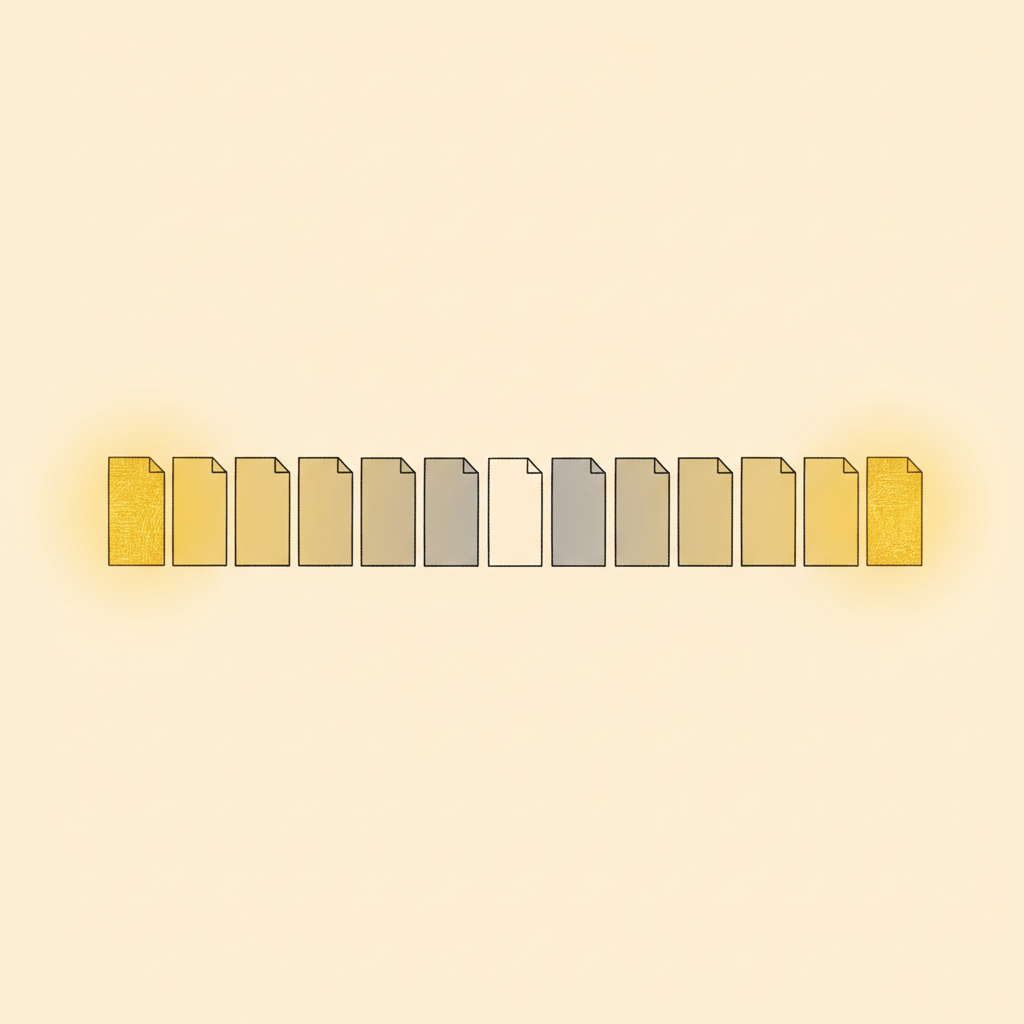
10 minThe Lost in the Middle Problem: Why LLMs Ignore What You Put in the Centre of Your Prompt
Liu et al. (2023) demonstrated that language model performance on multi-document QA degrades significantly when relevant information appears in the middle of a long context, even when models nominally support that context length. This 'lost in the middle' effect has direct, actionable consequences for how you structure RAG outputs, system prompts, and few-shot examples.